Introduction
A linear model makes predictions using:
θ T x
\theta^T x
θ T x For squared-error regression, a batch gradient descent update is:
θ ← θ + α ∑ i = 1 n ( y ( i ) − θ T x ( i ) ) x ( i )
\theta
\leftarrow
\theta
+
\alpha
\sum_{i=1}^{n}
\left(
y^{(i)}
-
\theta^T x^{(i)}
\right)
x^{(i)}
θ ← θ + α i = 1 ∑ n ( y ( i ) − θ T x ( i ) ) x ( i ) The problem is that a linear model can only represent linear relationships in the features we give it.
If the relationship is nonlinear, we can create new features using a feature map:
ϕ ( x )
\phi(x)
ϕ ( x ) Instead of using x x x ϕ ( x ) \phi(x) ϕ ( x )
θ ← θ + α ∑ i = 1 n ( y ( i ) − θ T ϕ ( x ( i ) ) ) ϕ ( x ( i ) )
\theta
\leftarrow
\theta
+
\alpha
\sum_{i=1}^{n}
\left(
y^{(i)}
-
\theta^T\phi(x^{(i)})
\right)
\phi(x^{(i)})
θ ← θ + α i = 1 ∑ n ( y ( i ) − θ T ϕ ( x ( i ) ) ) ϕ ( x ( i ) ) The model is still linear in the transformed features ϕ ( x ) \phi(x) ϕ ( x )
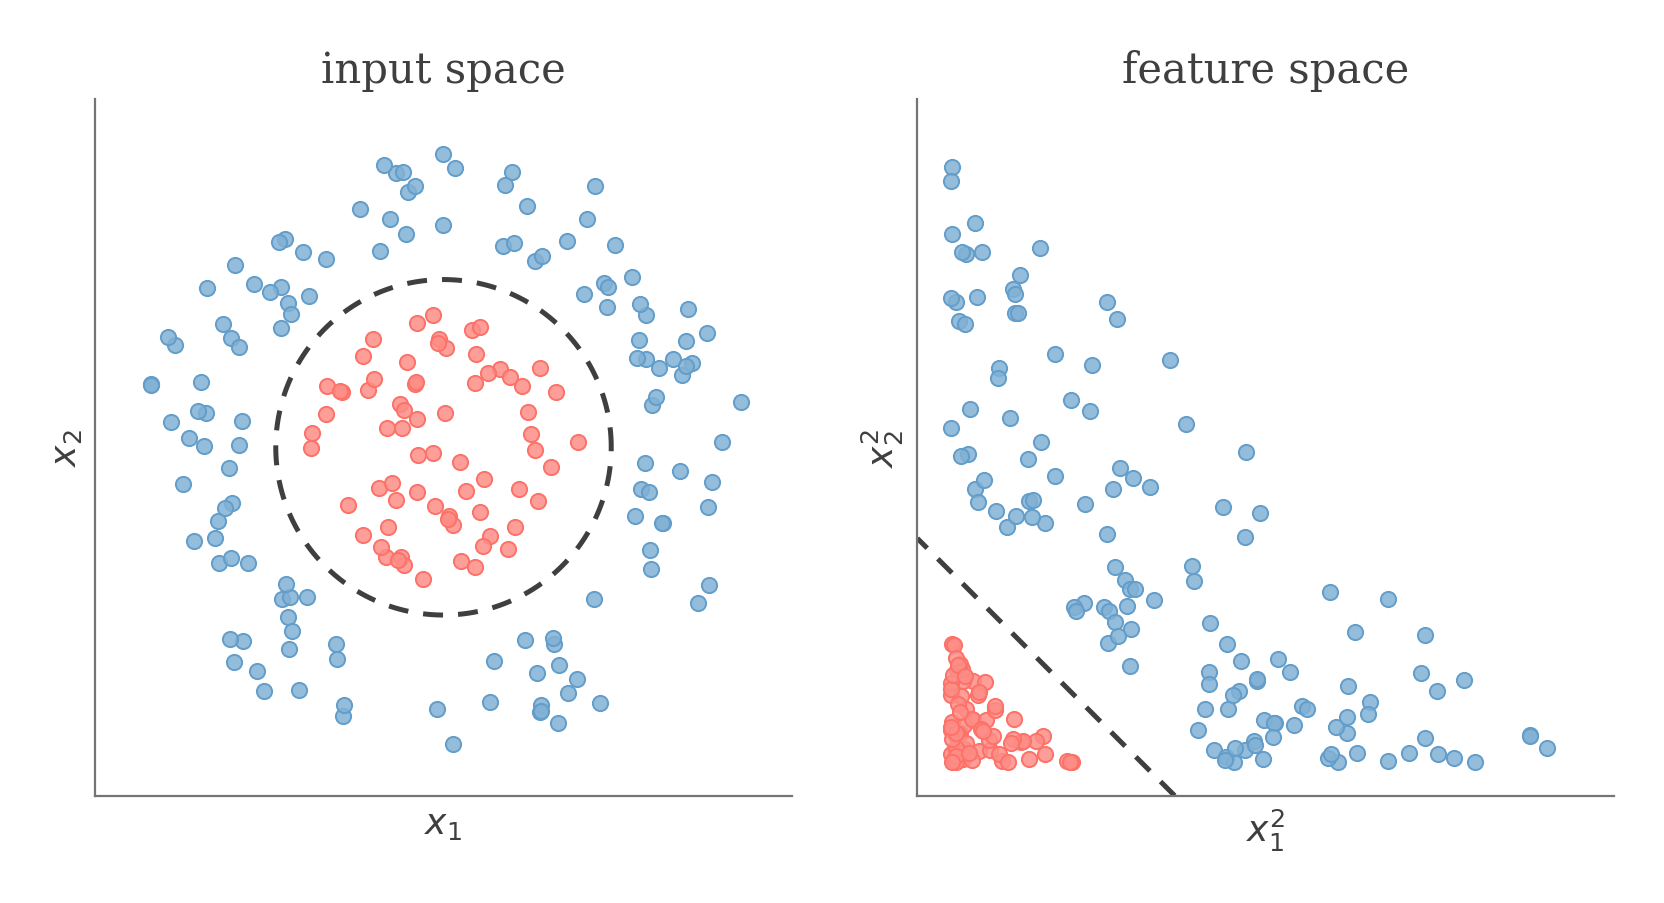
The same idea applies to classification.
A nonlinear boundary in the original input space can become a linear boundary after applying the feature map ϕ \phi ϕ
For example, mapping ( x 1 , x 2 ) (x_1,x_2) ( x 1 , x 2 ) ( x 1 2 , x 2 2 ) (x_1^2,x_2^2) ( x 1 2 , x 2 2 )
x 1 2 + x 2 2 = c
x_1^2+x_2^2=c
x 1 2 + x 2 2 = c into a linear boundary in the transformed feature space.
The drawback is that the transformed feature vector can become very large.
For example, suppose ϕ ( x ) \phi(x) ϕ ( x ) 3 3 3
1 + d + d 2 + d 3 = Θ ( d 3 )
1+d+d^2+d^3
=
\Theta(d^3)
1 + d + d 2 + d 3 = Θ ( d 3 ) So explicitly constructing ϕ ( x ) \phi(x) ϕ ( x ) θ \theta θ Θ ( d 3 ) \Theta(d^3) Θ ( d 3 )
The Kernel Trick
The key observation is that gradient descent never needs θ \theta θ
If we start with:
θ 0 = 0
\theta_0=0
θ 0 = 0 then every update adds a linear combination of the vectors ϕ ( x ( i ) ) \phi(x^{(i)}) ϕ ( x ( i ) ) θ \theta θ
θ = ∑ i = 1 n β i ϕ ( x ( i ) )
\theta
=
\sum_{i=1}^{n}
\beta_i
\phi(x^{(i)})
θ = i = 1 ∑ n β i ϕ ( x ( i ) ) Instead of storing θ \theta θ β i \beta_i β i
Substituting this representation into the gradient update gives an update for those coefficients.
› See derivationθ ← θ + α ∑ i = 1 n ( y ( i ) − θ T ϕ ( x ( i ) ) ) ϕ ( x ( i ) )
\theta
\leftarrow
\theta
+
\alpha
\sum_{i=1}^{n}
\left(
y^{(i)}
-
\theta^T\phi(x^{(i)})
\right)
\phi(x^{(i)})
θ ← θ + α i = 1 ∑ n ( y ( i ) − θ T ϕ ( x ( i ) ) ) ϕ ( x ( i ) ) = ∑ i = 1 n β i ϕ ( x ( i ) ) + α ∑ i = 1 n ( y ( i ) − θ T ϕ ( x ( i ) ) ) ϕ ( x ( i ) )
=
\sum_{i=1}^{n}
\beta_i\phi(x^{(i)})
+
\alpha
\sum_{i=1}^{n}
\left(
y^{(i)}
-
\theta^T\phi(x^{(i)})
\right)
\phi(x^{(i)})
= i = 1 ∑ n β i ϕ ( x ( i ) ) + α i = 1 ∑ n ( y ( i ) − θ T ϕ ( x ( i ) ) ) ϕ ( x ( i ) ) = ∑ i = 1 n [ β i + α ( y ( i ) − θ T ϕ ( x ( i ) ) ) ] ϕ ( x ( i ) )
=
\sum_{i=1}^{n}
\left[
\beta_i
+
\alpha
\left(
y^{(i)}
-
\theta^T\phi(x^{(i)})
\right)
\right]
\phi(x^{(i)})
= i = 1 ∑ n [ β i + α ( y ( i ) − θ T ϕ ( x ( i ) ) ) ] ϕ ( x ( i ) ) i Both sums use the same feature vectors ϕ ( x ( i ) ) \phi(x^{(i)}) ϕ ( x ( i ) )
Therefore:
β i ← β i + α ( y ( i ) − θ T ϕ ( x ( i ) ) )
\beta_i
\leftarrow
\beta_i
+
\alpha
\left(
y^{(i)}
-
\theta^T\phi(x^{(i)})
\right)
β i ← β i + α ( y ( i ) − θ T ϕ ( x ( i ) ) ) For a batch gradient step, all β i \beta_i β i
Now substitute:
θ = ∑ j = 1 n β j ϕ ( x ( j ) )
\theta
=
\sum_{j=1}^{n}
\beta_j\phi(x^{(j)})
θ = j = 1 ∑ n β j ϕ ( x ( j ) ) into the prediction term.
› See derivationθ T ϕ ( x ( i ) ) = ( ∑ j = 1 n β j ϕ ( x ( j ) ) ) T ϕ ( x ( i ) )
\theta^T\phi(x^{(i)})
=
\left(
\sum_{j=1}^{n}
\beta_j\phi(x^{(j)})
\right)^T
\phi(x^{(i)})
θ T ϕ ( x ( i ) ) = ( j = 1 ∑ n β j ϕ ( x ( j ) ) ) T ϕ ( x ( i ) ) = ∑ j = 1 n β j ϕ ( x ( j ) ) T ϕ ( x ( i ) )
=
\sum_{j=1}^{n}
\beta_j
\phi(x^{(j)})^T
\phi(x^{(i)})
= j = 1 ∑ n β j ϕ ( x ( j ) ) T ϕ ( x ( i ) ) i The inner product is linear, so the sum and coefficients can be moved outside.
This is the important result: the algorithm only needs inner products between transformed examples.
We define a kernel as this feature-space inner product:
K ( x , z ) = ϕ ( x ) T ϕ ( z ) = ⟨ ϕ ( x ) , ϕ ( z ) ⟩
K(x,z)
=
\phi(x)^T\phi(z)
=
\left\langle
\phi(x),
\phi(z)
\right\rangle
K ( x , z ) = ϕ ( x ) T ϕ ( z ) = ⟨ ϕ ( x ) , ϕ ( z ) ⟩ If K ( x , z ) K(x,z) K ( x , z ) x x x z z z ϕ ( x ) \phi(x) ϕ ( x )
This is the kernel trick.
The coefficient update becomes:
β i ← β i + α ( y ( i ) − ∑ j = 1 n β j K ( x ( i ) , x ( j ) ) )
\beta_i
\leftarrow
\beta_i
+
\alpha
\left(
y^{(i)}
-
\sum_{j=1}^{n}
\beta_j
K(x^{(i)},x^{(j)})
\right)
β i ← β i + α ( y ( i ) − j = 1 ∑ n β j K ( x ( i ) , x ( j ) ) ) For a fixed training set, we can store all pairwise kernel values in the Gram matrix:
K i j = K ( x ( i ) , x ( j ) )
K_{ij}
=
K(x^{(i)},x^{(j)})
K ij = K ( x ( i ) , x ( j ) ) This avoids recomputing the same kernel values on every iteration.
A feature-map example
Suppose our feature map contains all ordered products of degrees 0 0 0 3 3 3
Computing the inner product explicitly would require Θ ( d 3 ) \Theta(d^3) Θ ( d 3 ) ⟨ x , z ⟩ \langle x,z\rangle ⟨ x , z ⟩
› See derivation⟨ ϕ ( x ) , ϕ ( z ) ⟩ = 1 + ∑ i = 1 d x i z i + ∑ i , j x i x j z i z j + ∑ i , j , k x i x j x k z i z j z k
\left\langle
\phi(x),
\phi(z)
\right\rangle
=
1
+
\sum_{i=1}^{d}x_i z_i
+
\sum_{i,j}
x_i x_j z_i z_j
+
\sum_{i,j,k}
x_i x_j x_k z_i z_j z_k
⟨ ϕ ( x ) , ϕ ( z ) ⟩ = 1 + i = 1 ∑ d x i z i + i , j ∑ x i x j z i z j + i , j , k ∑ x i x j x k z i z j z k = 1 + ∑ i = 1 d x i z i + ( ∑ i = 1 d x i z i ) ( ∑ j = 1 d x j z j ) + ∑ i , j , k x i x j x k z i z j z k
=
1
+
\sum_{i=1}^{d}x_i z_i
+
\left(
\sum_{i=1}^{d}x_i z_i
\right)
\left(
\sum_{j=1}^{d}x_j z_j
\right)
+
\sum_{i,j,k}
x_i x_j x_k z_i z_j z_k
= 1 + i = 1 ∑ d x i z i + ( i = 1 ∑ d x i z i ) ( j = 1 ∑ d x j z j ) + i , j , k ∑ x i x j x k z i z j z k i The double sum factors because the i i i j j j
= 1 + ∑ i = 1 d x i z i + ( ∑ i = 1 d x i z i ) 2 + ( ∑ i = 1 d x i z i ) ( ∑ j = 1 d x j z j ) ( ∑ k = 1 d x k z k )
=
1
+
\sum_{i=1}^{d}x_i z_i
+
\left(
\sum_{i=1}^{d}x_i z_i
\right)^2
+
\left(
\sum_{i=1}^{d}x_i z_i
\right)
\left(
\sum_{j=1}^{d}x_j z_j
\right)
\left(
\sum_{k=1}^{d}x_k z_k
\right)
= 1 + i = 1 ∑ d x i z i + ( i = 1 ∑ d x i z i ) 2 + ( i = 1 ∑ d x i z i ) ( j = 1 ∑ d x j z j ) ( k = 1 ∑ d x k z k ) i The triple sum factors in the same way.
= 1 + ∑ i = 1 d x i z i + ( ∑ i = 1 d x i z i ) 2 + ( ∑ i = 1 d x i z i ) 3
=
1
+
\sum_{i=1}^{d}x_i z_i
+
\left(
\sum_{i=1}^{d}x_i z_i
\right)^2
+
\left(
\sum_{i=1}^{d}x_i z_i
\right)^3
= 1 + i = 1 ∑ d x i z i + ( i = 1 ∑ d x i z i ) 2 + ( i = 1 ∑ d x i z i ) 3 = 1 + ⟨ x , z ⟩ + ⟨ x , z ⟩ 2 + ⟨ x , z ⟩ 3
=
1
+
\langle x,z\rangle
+
\langle x,z\rangle^2
+
\langle x,z\rangle^3
= 1 + ⟨ x , z ⟩ + ⟨ x , z ⟩ 2 + ⟨ x , z ⟩ 3 So instead of constructing Θ ( d 3 ) \Theta(d^3) Θ ( d 3 ) O ( d ) O(d) O ( d )
K ( x , z ) = 1 + ⟨ x , z ⟩ + ⟨ x , z ⟩ 2 + ⟨ x , z ⟩ 3
K(x,z)
=
1
+
\langle x,z\rangle
+
\langle x,z\rangle^2
+
\langle x,z\rangle^3
K ( x , z ) = 1 + ⟨ x , z ⟩ + ⟨ x , z ⟩ 2 + ⟨ x , z ⟩ 3 The kernel trick avoids the cost of explicitly constructing a large feature vector, but it introduces a different cost: kernel methods often scale poorly with the number of training examples.
Storing the full Gram matrix requires:
O ( n 2 )
O(n^2)
O ( n 2 ) memory.
Prediction also requires only kernel evaluations. For a new input x x x
θ T ϕ ( x ) = ∑ i = 1 n β i K ( x ( i ) , x )
\theta^T\phi(x)
=
\sum_{i=1}^{n}
\beta_i
K(x^{(i)},x)
θ T ϕ ( x ) = i = 1 ∑ n β i K ( x ( i ) , x ) So both training and prediction can be carried out without explicitly computing ϕ ( x ) \phi(x) ϕ ( x )
Common Kernels
A kernel determines how two inputs are compared in feature space.
Common choices include:
K l i n e a r ( x , z ) = x T z
K_{\mathrm{linear}}(x,z)
=
x^Tz
K linear ( x , z ) = x T z K p o l y n o m i a l ( x , z ) = ( x T z + c ) p , p ∈ N , c ≥ 0
K_{\mathrm{polynomial}}(x,z)
=
(x^Tz+c)^p,
\qquad
p\in\mathbb{N},
\quad
c\geq0
K polynomial ( x , z ) = ( x T z + c ) p , p ∈ N , c ≥ 0 K R B F ( x , z ) = exp ( − ∥ x − z ∥ 2 2 2 σ 2 ) , σ > 0
K_{\mathrm{RBF}}(x,z)
=
\exp
\left(
-\frac{\|x-z\|_2^2}{2\sigma^2}
\right),
\qquad
\sigma>0
K RBF ( x , z ) = exp ( − 2 σ 2 ∥ x − z ∥ 2 2 ) , σ > 0 The linear kernel is just the ordinary dot product, so it does not introduce nonlinear features.
The polynomial kernel allows the model to use interactions between features up to degree p p p c > 0 c>0 c > 0
The RBF kernel gives high similarity to nearby points and low similarity to distant points. It corresponds to an infinite-dimensional feature space.
The polynomial degree p p p σ \sigma σ
Feature scaling is especially important for polynomial and RBF kernels because both depend strongly on feature magnitudes or distances.
Kernel Ridge Regression
The kernel trick is not a learning algorithm by itself. It is a way to rewrite algorithms so that they depend only on kernel evaluations.
Kernel ridge regression is one example.
It fits the training data using squared error while penalizing overly complex functions:
f ∗ = arg min f ∈ H K [ ∑ i = 1 n ( y ( i ) − f ( x ( i ) ) ) 2 + λ ∥ f ∥ H K 2 ] , λ > 0
f^*
=
\arg\min_{f\in\mathcal{H}_K}
\left[
\sum_{i=1}^{n}
\left(
y^{(i)}-f(x^{(i)})
\right)^2
+
\lambda
\|f\|_{\mathcal{H}_K}^2
\right],
\qquad
\lambda>0
f ∗ = arg f ∈ H K min [ i = 1 ∑ n ( y ( i ) − f ( x ( i ) ) ) 2 + λ ∥ f ∥ H K 2 ] , λ > 0 The representer theorem tells us that the solution can always be written using the training examples:
f ( x ) = ∑ i = 1 n α i K ( x ( i ) , x )
f(x)
=
\sum_{i=1}^{n}
\alpha_i
K(x^{(i)},x)
f ( x ) = i = 1 ∑ n α i K ( x ( i ) , x ) Let K ∈ R n × n K\in\mathbb{R}^{n\times n} K ∈ R n × n
K i j = K ( x ( i ) , x ( j ) )
K_{ij}
=
K(x^{(i)},x^{(j)})
K ij = K ( x ( i ) , x ( j ) ) and let:
y = [ y ( 1 ) ⋮ y ( n ) ]
y
=
\begin{bmatrix}
y^{(1)} \\
\vdots \\
y^{(n)}
\end{bmatrix}
y = y ( 1 ) ⋮ y ( n ) The optimal coefficients satisfy:
( K + λ I ) α = y
(K+\lambda I)\alpha
=
y
( K + λ I ) α = y We solve this linear system for α \alpha α
For a new input x x x
k x = [ K ( x ( 1 ) , x ) ⋮ K ( x ( n ) , x ) ]
k_x
=
\begin{bmatrix}
K(x^{(1)},x) \\
\vdots \\
K(x^{(n)},x)
\end{bmatrix}
k x = K ( x ( 1 ) , x ) ⋮ K ( x ( n ) , x ) Prediction is then:
f ( x ) = k x T α
f(x)
=
k_x^T\alpha
f ( x ) = k x T α The parameter λ \lambda λ
A larger λ \lambda λ λ \lambda λ
Because λ > 0 \lambda>0 λ > 0
K + λ I
K+\lambda I
K + λ I is positive definite even when K K K
A direct solve takes:
O ( n 3 )
O(n^3)
O ( n 3 ) time, while storing the Gram matrix requires:
O ( n 2 )
O(n^2)
O ( n 2 ) memory.
This motivates approximate kernel methods for large datasets.
Validity of Kernels
Not every similarity function can be used as a kernel.
A valid kernel must behave like an inner product in some feature space.
More formally, K ( x , z ) K(x,z) K ( x , z )
x ( 1 ) , … , x ( n )
x^{(1)},\ldots,x^{(n)}
x ( 1 ) , … , x ( n ) the Gram matrix:
K i j = K ( x ( i ) , x ( j ) )
K_{ij}
=
K(x^{(i)},x^{(j)})
K ij = K ( x ( i ) , x ( j ) ) must be positive semidefinite.
Equivalently, there must exist a feature map ϕ \phi ϕ
K ( x , z ) = ⟨ ϕ ( x ) , ϕ ( z ) ⟩
K(x,z)
=
\left\langle
\phi(x),
\phi(z)
\right\rangle
K ( x , z ) = ⟨ ϕ ( x ) , ϕ ( z ) ⟩ One way to prove that a kernel is valid is to explicitly construct such a feature map.
Consider the quadratic kernel:
K ( x , z ) = ( x T z + c ) 2 , c ≥ 0
K(x,z)
=
(x^Tz+c)^2,
\qquad
c\geq0
K ( x , z ) = ( x T z + c ) 2 , c ≥ 0 For x ∈ R 3 x\in\mathbb{R}^3 x ∈ R 3
ϕ ( x ) = [ x 1 2 x 2 2 x 3 2 2 x 1 x 2 2 x 1 x 3 2 x 2 x 3 2 c x 1 2 c x 2 2 c x 3 c ]
\phi(x)
=
\begin{bmatrix}
x_1^2 \\
x_2^2 \\
x_3^2 \\
\sqrt{2}x_1x_2 \\
\sqrt{2}x_1x_3 \\
\sqrt{2}x_2x_3 \\
\sqrt{2c}x_1 \\
\sqrt{2c}x_2 \\
\sqrt{2c}x_3 \\
c
\end{bmatrix}
ϕ ( x ) = x 1 2 x 2 2 x 3 2 2 x 1 x 2 2 x 1 x 3 2 x 2 x 3 2 c x 1 2 c x 2 2 c x 3 c Its inner product reproduces the kernel.
› See derivationϕ ( x ) T ϕ ( z ) = x 1 2 z 1 2 + x 2 2 z 2 2 + x 3 2 z 3 2
\phi(x)^T\phi(z)
=
x_1^2z_1^2
+
x_2^2z_2^2
+
x_3^2z_3^2
ϕ ( x ) T ϕ ( z ) = x 1 2 z 1 2 + x 2 2 z 2 2 + x 3 2 z 3 2 + 2 x 1 x 2 z 1 z 2 + 2 x 1 x 3 z 1 z 3 + 2 x 2 x 3 z 2 z 3
\quad
+
2x_1x_2z_1z_2
+
2x_1x_3z_1z_3
+
2x_2x_3z_2z_3
+ 2 x 1 x 2 z 1 z 2 + 2 x 1 x 3 z 1 z 3 + 2 x 2 x 3 z 2 z 3 + 2 c ∑ i = 1 3 x i z i + c 2
\quad
+
2c
\sum_{i=1}^{3}
x_i z_i
+
c^2
+ 2 c i = 1 ∑ 3 x i z i + c 2 = ( ∑ i = 1 3 x i z i ) 2 + 2 c ( ∑ i = 1 3 x i z i ) + c 2
=
\left(
\sum_{i=1}^{3}
x_i z_i
\right)^2
+
2c
\left(
\sum_{i=1}^{3}
x_i z_i
\right)
+
c^2
= ( i = 1 ∑ 3 x i z i ) 2 + 2 c ( i = 1 ∑ 3 x i z i ) + c 2 i Expanding ( x T z ) 2 (x^Tz)^2 ( x T z ) 2 2 2 2
= ( x T z ) 2 + 2 c ( x T z ) + c 2
=
(x^Tz)^2
+
2c(x^Tz)
+
c^2
= ( x T z ) 2 + 2 c ( x T z ) + c 2 = ( x T z + c ) 2
=
(x^Tz+c)^2
= ( x T z + c ) 2 = K ( x , z )
=
K(x,z)
= K ( x , z ) Therefore, this is a valid kernel.
More generally, every valid kernel must produce a positive-semidefinite Gram matrix for every finite set of inputs.
For any coefficient vector a a a
a T K a ≥ 0
a^TKa
\geq
0
a T K a ≥ 0 To see why, suppose:
K ( x , z ) = ϕ ( x ) T ϕ ( z )
K(x,z)
=
\phi(x)^T\phi(z)
K ( x , z ) = ϕ ( x ) T ϕ ( z ) Then:
› See derivationa T K a = ∑ i ∑ j a i K i j a j
a^TKa
=
\sum_i
\sum_j
a_i
K_{ij}
a_j
a T K a = i ∑ j ∑ a i K ij a j = ∑ i ∑ j a i ϕ ( x ( i ) ) T ϕ ( x ( j ) ) a j
=
\sum_i
\sum_j
a_i
\phi(x^{(i)})^T
\phi(x^{(j)})
a_j
= i ∑ j ∑ a i ϕ ( x ( i ) ) T ϕ ( x ( j ) ) a j = ∑ i ∑ j a i ( ∑ k ϕ k ( x ( i ) ) ϕ k ( x ( j ) ) ) a j
=
\sum_i
\sum_j
a_i
\left(
\sum_k
\phi_k(x^{(i)})
\phi_k(x^{(j)})
\right)
a_j
= i ∑ j ∑ a i ( k ∑ ϕ k ( x ( i ) ) ϕ k ( x ( j ) ) ) a j = ∑ k ( ∑ i a i ϕ k ( x ( i ) ) ) ( ∑ j a j ϕ k ( x ( j ) ) )
=
\sum_k
\left(
\sum_i
a_i
\phi_k(x^{(i)})
\right)
\left(
\sum_j
a_j
\phi_k(x^{(j)})
\right)
= k ∑ ( i ∑ a i ϕ k ( x ( i ) ) ) ( j ∑ a j ϕ k ( x ( j ) ) ) i Reordering the sums and grouping together all terms involving the same feature coordinate k k k
= ∑ k ( ∑ i a i ϕ k ( x ( i ) ) ) 2
=
\sum_k
\left(
\sum_i
a_i
\phi_k(x^{(i)})
\right)^2
= k ∑ ( i ∑ a i ϕ k ( x ( i ) ) ) 2 ≥ 0
\geq
0
≥ 0 The final expression is a sum of squares, so it can never be negative. This is why any kernel that corresponds to an inner product produces a positive-semidefinite Gram matrix.